If you're building with Claude Code, n8n, or AI agents in production, this is the email I'd want. Weekly recap of what shipped, what broke, and how I'm running it. Specific over vague. Replies welcome.
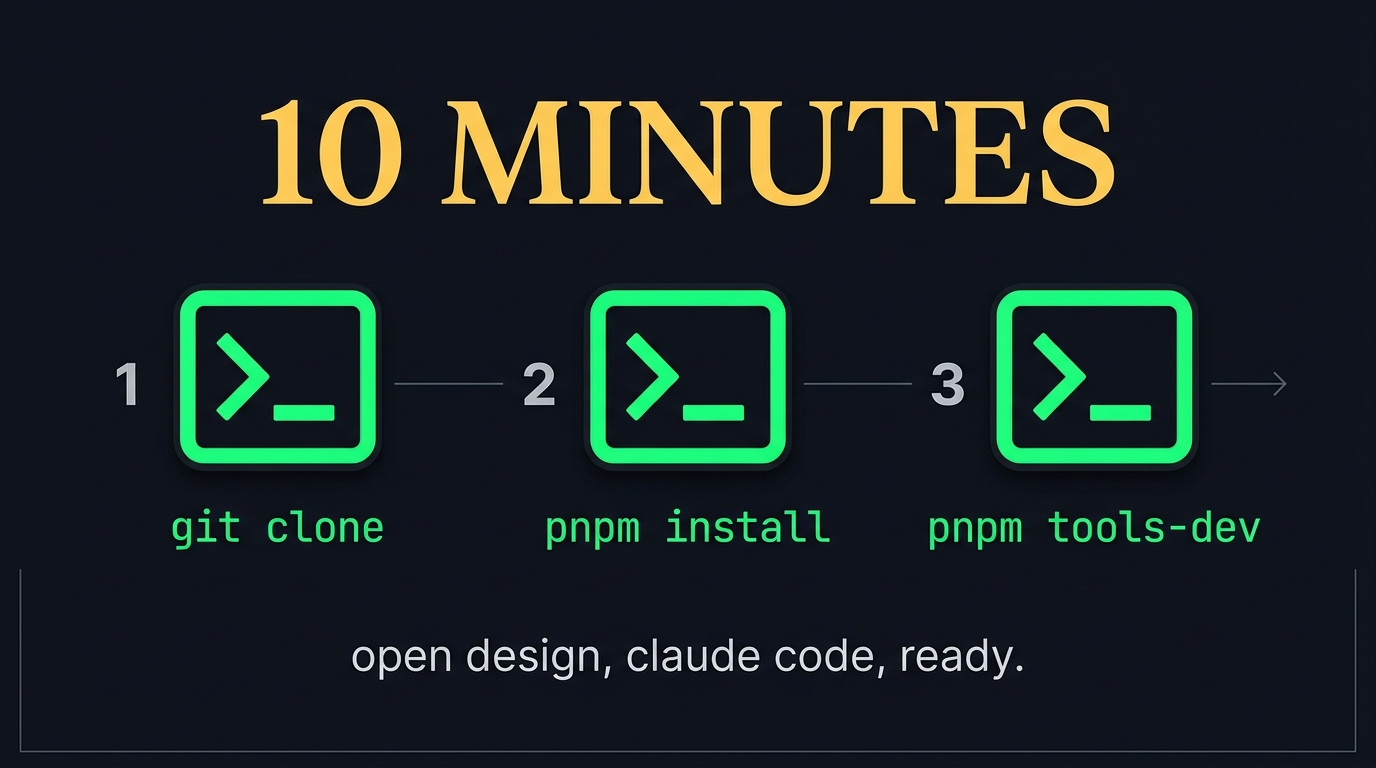
Open Design, running in 10 minutes
|
WotAI
If you're building with Claude Code, n8n, or AI agents in production, this is the email I'd want. Weekly recap of what shipped, what broke, and how I'm running it. Specific over vague. Replies welcome.
Claude, GPT-5 and Kimi, tested on the same 150 judgments Only four of the sixteen will admit when they are not sure. Claude, GPT-5 and Kimi, tested on the same 150 judgments Jev is the only sub-second model that will tell you it doesn't know TypeSafe shipped a model this week that returns calibrated probabilities instead of text, so I ran it against fifteen others on the same 150 judgments. It finished tenth on accuracy. I threw away two headlines before the data stopped contradicting me: the...
AGENTS.md vs CLAUDE.md, tested on 13 repos 12 of mine load it. One never did, and I didn't notice for a month. AGENTS.md vs CLAUDE.md, tested on 13 repos Hey there, I have 13 repos that carry both an AGENTS.md and a CLAUDE.md. This week I checked how each one wires them together, expecting 13 identical answers. Twelve import AGENTS.md on line one of CLAUDE.md. One asks the agent, in a sentence, to please go read it. That one holds 6,479 bytes of branch rules and load-bearing invariants that...
This Claude Code plugin loads before you type It installs itself into every session, then quietly wins six skills. Plus 2 more reads. This Claude Code plugin loads before you type Hey there, I have both of the big Claude Code process plugins installed in the same repo. It took me a while to notice that six of their skills do the exact same job. Nobody warns you about that, and the thing that decides which one wins is smaller than you would expect. Six Claude Code skills collide, and one hook...