Claude, GPT-5 and Kimi, tested on the same 150 judgments


Claude, GPT-5 and Kimi, tested on the same 150 judgments
Only four of the sixteen will admit when they are not sure.  ‌ ‌ ‌ ‌ ‌ ‌ ‌ ‌ ‌ ‌
WotAI

Claude, GPT-5 and Kimi, tested on the same 150 judgments

Jev is the only sub-second model that will tell you it doesn't know

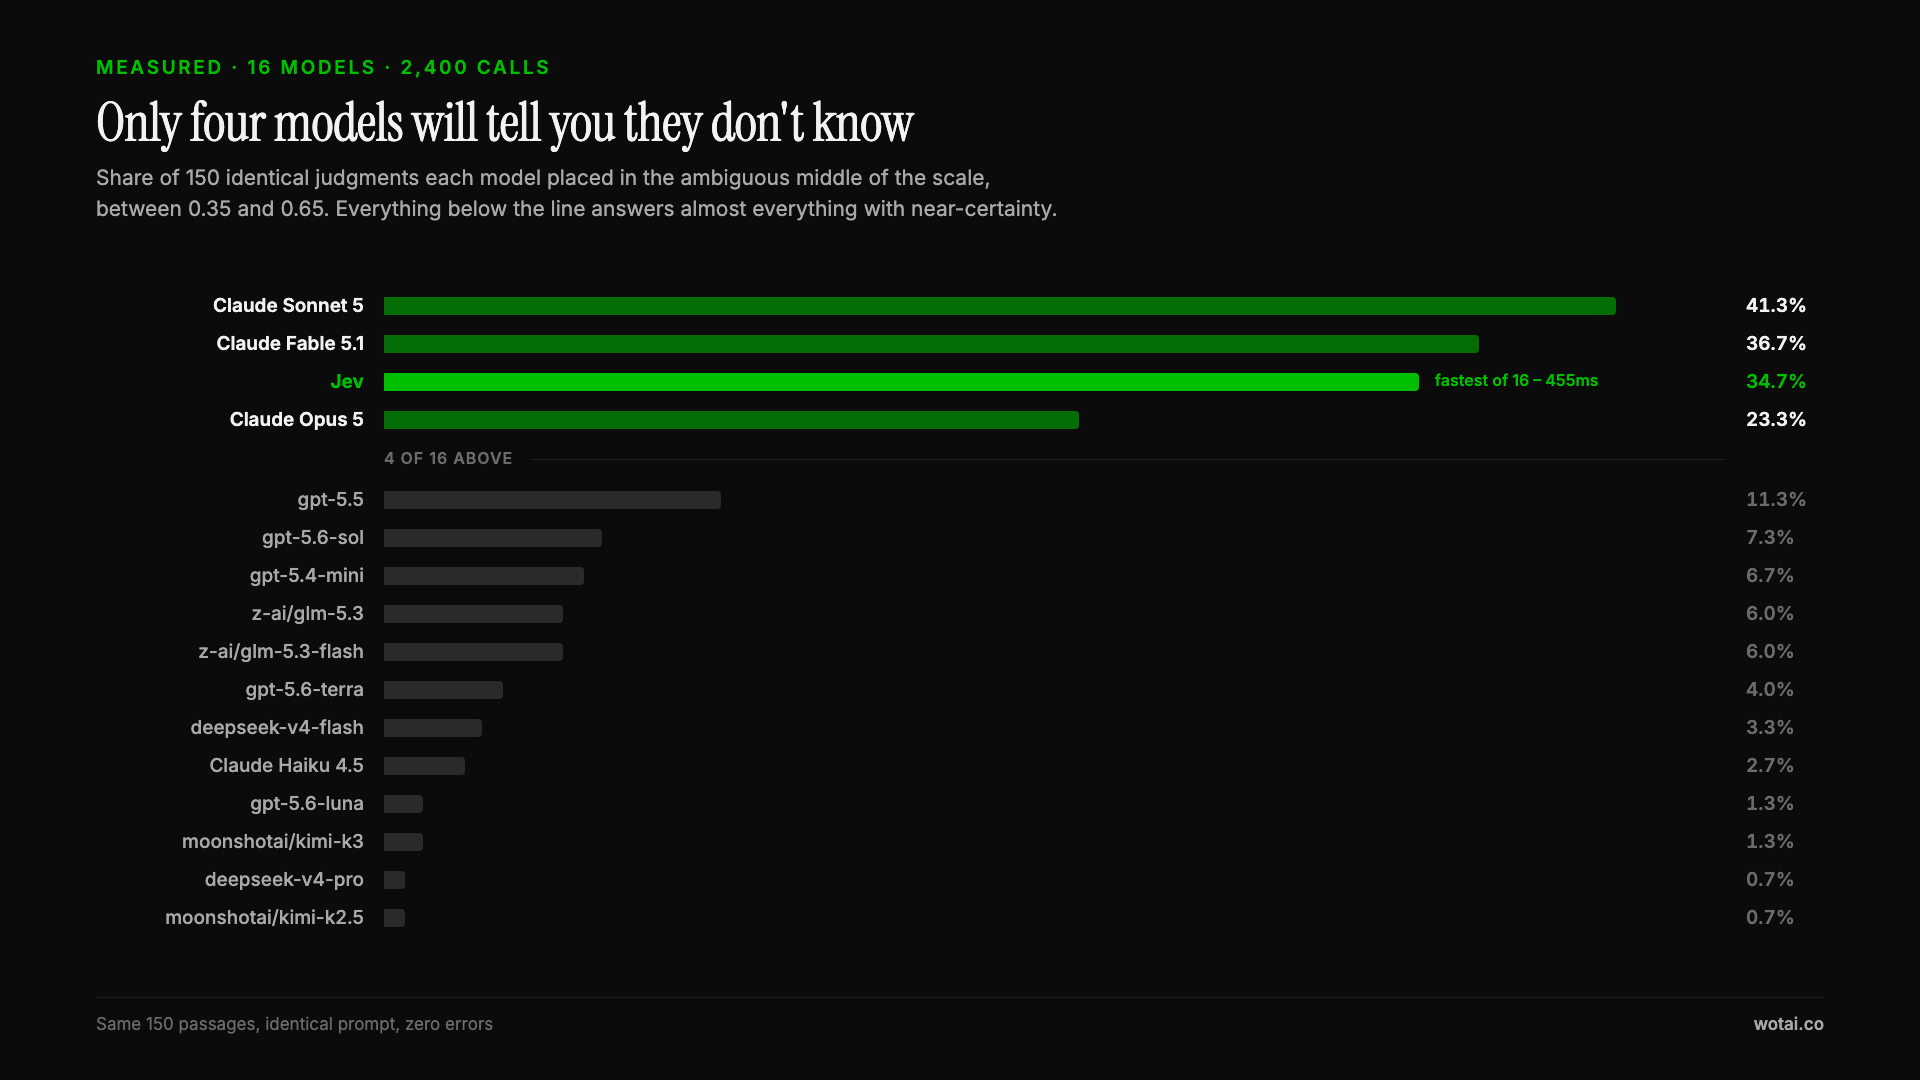
Only four of sixteen models will tell you they don't know – a ranked bar chart of how often each model places an answer in the ambiguous middle

TypeSafe shipped a model this week that returns calibrated probabilities instead of text, so I ran it against fifteen others on the same 150 judgments. It finished tenth on accuracy. I threw away two headlines before the data stopped contradicting me: the first said Haiku was more accurate, which held on exactly one task, and the second said Jev's confidence was usable and Haiku's was not, which died the moment I computed calibration error properly and got 0.121 against 0.122.

What survived is a column I almost did not measure. Only four of the sixteen models will place an answer in the ambiguous middle of the probability scale. Everything else answers almost everything at near-certainty, and price does not predict which is which – the most expensive model in the set finished last on accuracy and last on calibration, while the cheapest ran the whole benchmark for $0.003 and beat Jev outright. If your code escalates uncertain rows to a human, that rule fires on 34.7% of Jev's rows and 2.7% of Haiku's. The ambiguous rows did not go anywhere; they just went through.

Read the 16-model benchmark →


Reply and tell me what your code does with a row it is unsure about. I read every reply.

– Alex

P.S. – I put the Claude Code hook that came out of this in a public repo: wotai-dev/typesafe-jev-tools. It fires on Write and Edit and asks whether the decision needs a model at all. The conversations behind reads like these happen in the WotAI Skool community. 760+ builders, three live calls a week, free to jump in.

Come build with us

Follow WotAI: LinkedIn  ·  YouTube  ·  TikTok
You are receiving this because you subscribed to the WotAI newsletter. Unsubscribe

WotAI · AI Automation that Actually Ships

wotai.co

WotAI · 440 N. Barranca Ave., Unit 3777, Covina, CA 91723

WotAI

If you're building with Claude Code, n8n, or AI agents in production, this is the email I'd want. Weekly recap of what shipped, what broke, and how I'm running it. Specific over vague. Replies welcome.

Read more from WotAI

AGENTS.md vs CLAUDE.md, tested on 13 repos 12 of mine load it. One never did, and I didn't notice for a month. AGENTS.md vs CLAUDE.md, tested on 13 repos Hey there, I have 13 repos that carry both an AGENTS.md and a CLAUDE.md. This week I checked how each one wires them together, expecting 13 identical answers. Twelve import AGENTS.md on line one of CLAUDE.md. One asks the agent, in a sentence, to please go read it. That one holds 6,479 bytes of branch rules and load-bearing invariants that...

This Claude Code plugin loads before you type

This Claude Code plugin loads before you type It installs itself into every session, then quietly wins six skills. Plus 2 more reads. This Claude Code plugin loads before you type Hey there, I have both of the big Claude Code process plugins installed in the same repo. It took me a while to notice that six of their skills do the exact same job. Nobody warns you about that, and the thing that decides which one wins is smaller than you would expect. Six Claude Code skills collide, and one hook...

Claude Code edited my video

Claude Code edited my video I never opened the timeline once, and the spec became the whole job. Plus 2 more reads. Claude Code edited my video Hey Reader, Three reads this week, and two of them are about the same quiet shift: the tool got good enough that the bottleneck moved somewhere less glamorous. An agent that can drive a video timeline still cannot decide what belongs on it. A workflow that looks automatable can still be the wrong one to touch first. I let Claude Code edit a video, and...